Cost Optimization
35 guides in this topicMost teams overspend on GPU compute by 40 to 60 percent, and it's rarely because the hourly rate is wrong. It's idle capacity, the wrong billing model, or a workload that could run on a smaller GPU than the one it's on. This cluster is the fix for that: practical cost engineering, not pricing comparisons, which live in the GPU Pricing cluster instead.
Topics range from billing-model selection (serverless versus on-demand versus reserved, when spot's 40-80% discount is worth the interruption risk) to hardware right-sizing (fractional GPUs with MIG, MPS, and vGPU, heterogeneous inference that splits prefill and decode across different GPU types) to the costs teams miss entirely: egress fees, electricity draw, and the multiplied token cost of agentic workloads that burn 5 to 30 times more tokens than a single chat completion.
The pillar post, The GPU Cloud Cost Optimization Playbook, ties these together into one framework covering instance selection, spot strategy, and idle-GPU elimination. Read it first for the overall approach, then use the specific posts here, spot arbitrage, FinOps chargeback, rent-vs-buy TCO, for the piece of your bill that's actually the problem.
Start Here
All Cost Optimization Guides
GPU Cluster Profit Margin Calculator by Utilization (2026)
Oct 17, 2026
GPU Refresh Cycle Rental: How Fast H100s and H200s Lose Value
Oct 9, 2026
Funding a GPU Buildout: Financing & Offtake Deals (2026)
Oct 9, 2026
RAG Inference Cost Calculator: Cost Per Token, Broken Down (2026)
Sep 29, 2026
Cost Per Token Vision Model: Image Tokens Cost More
Sep 23, 2026
LLM API Cost Comparison: The Real Cost Per Token Formula
Sep 17, 2026
LoRA Inference Cost Optimization: Shared vs Dedicated GPUs
Sep 14, 2026
Cost Per Million Tokens: How to Calculate Your Inference Bill
Sep 3, 2026
Spot GPU Instances in 2026: How Much You Save (and What Breaks)
Aug 30, 2026
AWS SageMaker Alternatives 2026: Cost & Migration Guide
Aug 25, 2026
Weights & Biases Pricing vs Self-Hosted MLflow (2026)
Aug 18, 2026
NVIDIA NIM Pricing vs Self-Hosted vLLM: Worth It? (2026)
Aug 11, 2026
Agentic AI Inference Cost: Why Agents Burn 5-30x Tokens
Jul 16, 2026
GPU Cluster Reservation Contracts: How to Negotiate in 2026
Jul 13, 2026
Free GPU Cloud Credits: 9 Programs That Changed in 2026
Jun 30, 2026
GPU Spot Instance Arbitrage: Bidding, Failover, Forecasting (2026)
Jun 3, 2026
GPU Cloud FinOps for AI Teams: Cost Allocation, Per-Project Chargeback, and Tag-Based Budgeting (2026)
Jun 2, 2026
GPU Cloud Egress Costs: The Hidden AI Bandwidth Bill (2026)
May 27, 2026
AI Inference Power Consumption and GPU Electricity Costs: 2026 Guide
Apr 20, 2026
Heterogeneous GPU Inference: Mix GPU Types to Cut Costs by 40% (2026)
Apr 17, 2026
How to Avoid Unexpected AWS Costs and Rethink Your GPU Infrastructure
Apr 16, 2026
How to Plan, Source and Optimize GPU Capacity for AI Deployment
Apr 16, 2026
Should You Rent or Buy GPUs? The 3-Year TCO Math for AI Training
Apr 16, 2026
AI GPU Buyers Guide 2026: How to Evaluate Cloud GPU Providers
Apr 15, 2026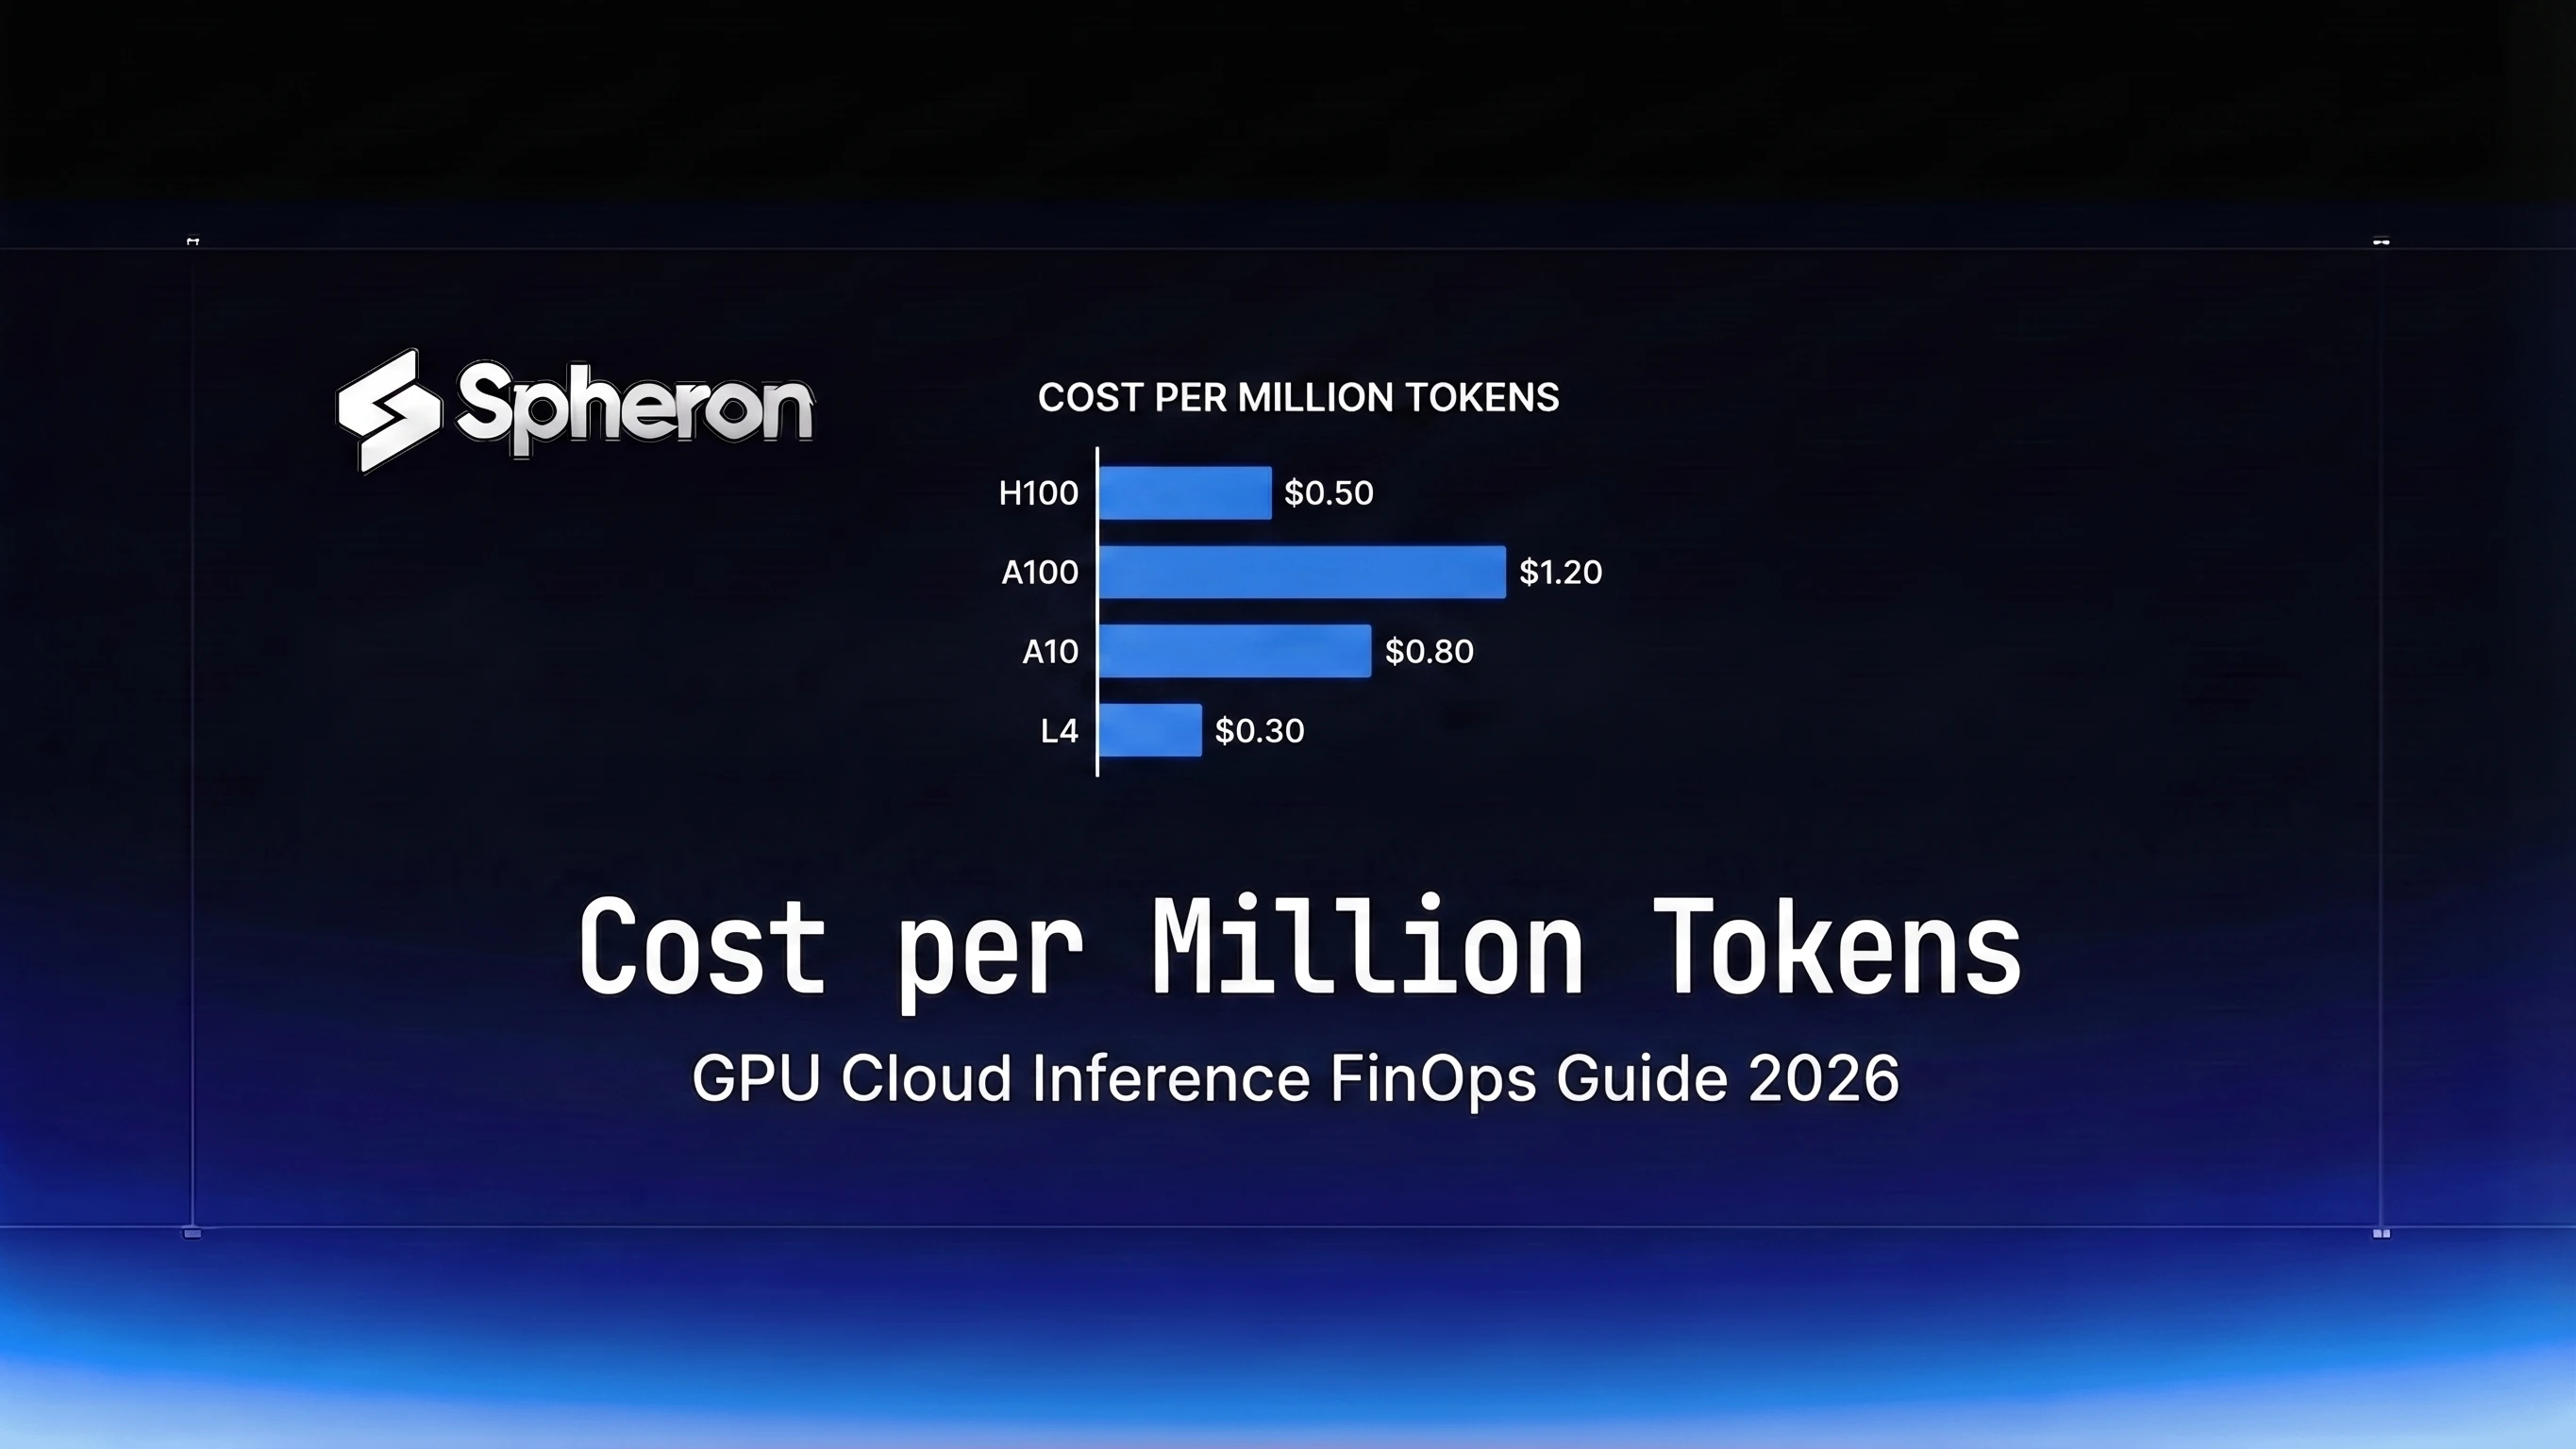
Token Factory on GPU Cloud: Maximize Tokens per Watt for AI Inference Revenue (2026 Guide)
Apr 13, 2026
GPU Shortage 2026: How to Secure AI Compute When GPUs Are Sold Out
Apr 6, 2026
Fractional GPUs for AI Inference: vGPU, MPS, and Right-Sizing Your GPU Cloud Spend (2026 Guide)
Apr 5, 2026
AI Inference Cost Economics in 2026: GPU FinOps Playbook
Apr 4, 2026
Run Multiple LLMs on One GPU: MIG, Time-Slicing, and MPS Guide
Mar 26, 2026
Serverless vs On-Demand vs Reserved GPU: Choose the Right Billing Model (Save 40-80%)
Mar 23, 2026
Multi-Node GPU Training Without InfiniBand: Tradeoffs and Cost Analysis
Mar 16, 2026
GPU Cloud for Startups in 2026: How to Get H100 Access Without a Sales Call
Mar 15, 2026Try It on Real GPUs
The GPUs behind these guides are the ones you can rent here: H100s, H200s, B200s, and more, billed per minute after a 20-minute minimum runtime, with no contracts. Pick one and you are live in under two minutes.
